The Synopsis
Cerebras Systems enables the training and deployment of trillion-parameter models on its custom wafer-scale hardware. By moving away from traditional GPU clusters, the company provides a path for enterprises to achieve model scale and challenges the compute-constrained status quo in the industry.
Cerebras Systems is moving the technical ceiling for AI development from simple parameter counts to the raw ability to train models previously thought impossible. The Silicon Valley hardware firm is challenging the industry standard of linking thousands of GPUs together. By deploying trillion-parameter models on its specialized hardware, the company is showing that large-scale intelligence relies on monolithic silicon design.
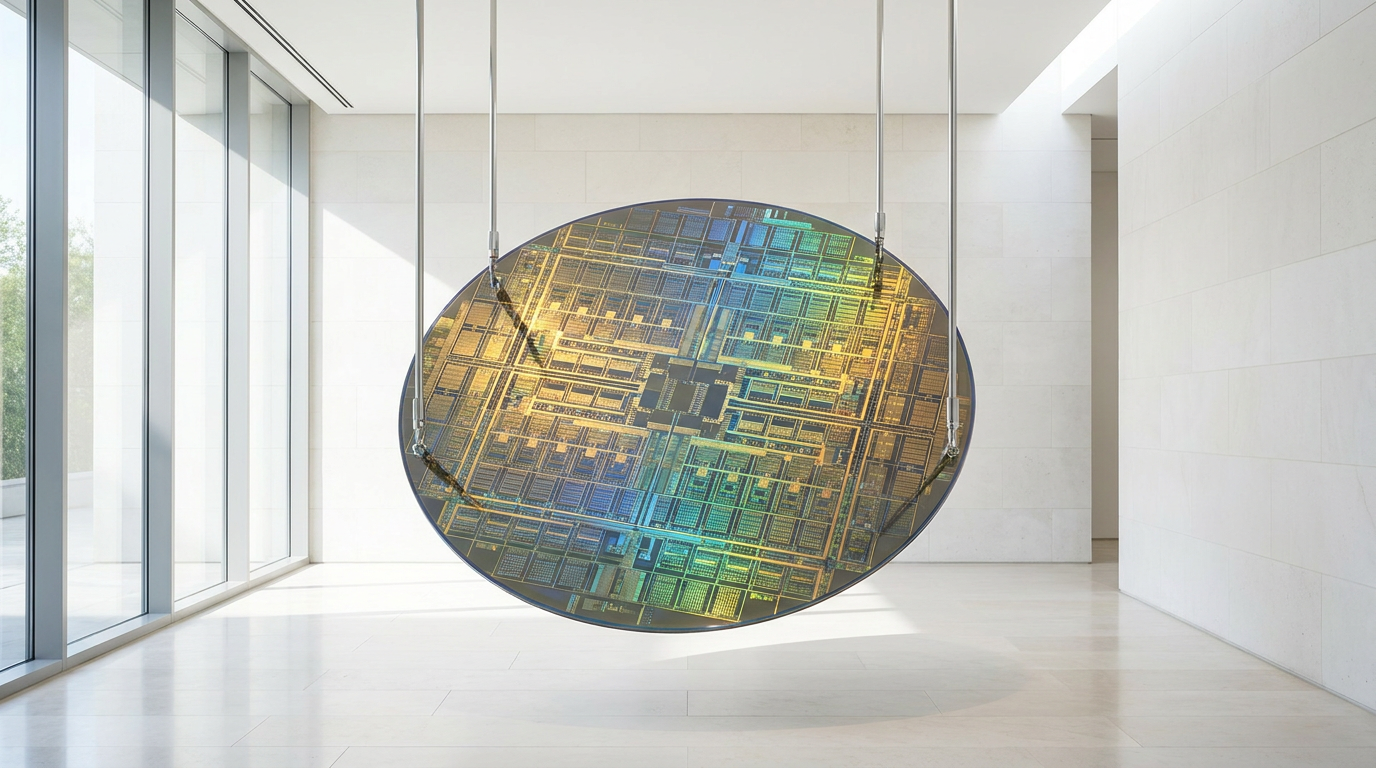
For years, the industry relied on distributed GPU clusters, a dependency that companies like OpenAI managed through massive funding rounds. Cerebras is taking a different route. Its wafer-scale engines treat the entire silicon wafer as a single, unified processor, which avoids the latency bottlenecks found in traditional data centers.
The move to trillion-parameter capabilities is a measurable turning point. As organizations look for ways to scale without hitting the wall of diminishing returns, Cerebras provides a new baseline. This is a strategy where compute efficiency, rather than pure capital expenditure, dictates the next generation of AI performance.
Cerebras Systems enables the training and deployment of trillion-parameter models on its custom wafer-scale hardware. By moving away from traditional GPU clusters, the company provides a path for enterprises to achieve model scale and challenges the compute-constrained status quo in the industry.
The Hardware Leap
The Physics of Scale
Cerebras Systems is changing high-performance computing with its Wafer-Scale Engine (WSE). The architecture puts hundreds of thousands of cores on one piece of silicon, which is a departure from the standard approach of stitching together thousands of individual GPUs. This traditional method creates communication latency and operational overhead that slows down training cycles.
Cerebras keeps the entire model on a single, massive processor to minimize the network-in-the-middle problem that has long hindered scaling. This architecture allows for training speeds that were previously theoretical. Because the industry struggles with the complexity of models that are difficult to interpret, as noted in recent research, a unified compute fabric makes experimentation faster, cheaper, and more efficient.
Beyond the Billion-Parameter Barrier
For researchers, this hardware allows them to push past the billion-parameter barrier without the logistical difficulty of managing distributed training jobs. The shift to trillion-parameter models is not just about size. It is about the emergent capabilities that arise when models have enough computational headroom to process massive, multi-modal datasets.
This development comes at a specific time. The capital flowing into the sector requires hardware that matches the ambition of top-tier AI labs. Cerebras provides the infrastructure that turns billions of dollars into functional, massive-scale models.
Impact on Builders
Democratizing Super-Computing
The timing of the Cerebras deployment is notable. While leaders like OpenAI adjust their development timelines, Cerebras is accelerating. They provide tools for smaller, specialized teams to attempt projects once restricted to the most well-funded labs on the planet.
Accessibility is key to a healthy ecosystem. By shortening the time to train, Cerebras is democratizing access to supercomputer-scale performance. Faster training cycles mean teams can iterate more frequently, test more hypotheses, and achieve product-market fit more effectively.
From Training to Real-World Agency
Deployment at this scale requires inference capabilities that are just as strong. Developers use platforms like Enso for agentic workflows to orchestrate these massive models in real time, which connects training to production. The ability to deploy a trillion-parameter model is a competitive advantage that will define the next cycle of the AI industry.
The transition occurs across the entire stack, from model training to the AI guardrails that maintain accuracy. Cerebras provides the raw compute power that is the foundation for the next wave of intelligent, agentic systems.
Future Directions for Wafer-Scale Computing
Efficiency at Scale
Traditional data centers face physical limits regarding cooling and power distribution once clusters reach thousands of nodes. Cerebras manages this by consolidating the workload. This integration reduces the energy overhead usually lost to inter-GPU communication.
Wafer-scale systems use less power than massive server racks, which is a primary selling point for sustainability-focused enterprises. Lower heat generation and higher core density allow for a smaller physical footprint in data center facilities.
Simplifying the Software Stack
Moving from distributed systems to wafer-scale engines simplifies the software stack. Engineers spend less time debugging inter-node communication errors or managing complex sharding strategies across thousands of devices. Because the hardware handles the orchestration, researchers focus on model architecture.
This shift in focus, from infrastructure maintenance to creative model building, may accelerate the speed of AI breakthroughs by allowing smaller teams to compete with tech conglomerates.
The Memory Bandwidth Advantage
As models grow, memory bandwidth often becomes the primary constraint rather than raw compute power. Standard GPUs are limited by the speed at which they can pull data from external memory. The Cerebras design integrates memory directly onto the wafer, placing it in immediate proximity to the compute cores.
This memory-centric architecture allows for higher throughput, which is necessary to process high-dimensional data quickly. For trillion-parameter models, this reduction in memory latency prevents the hardware from sitting idle while waiting for data.
Reliability in Large-Scale Training
Beyond pure speed, the reliability of a single-processor design is a major factor. In a cluster of thousands of GPUs, the probability of at least one device failing during a long training run is high, which forces checkpoints and restarts that waste time. A unified wafer reduces the number of failure points.
Research teams working under strict deadlines need this consistency. Fewer hardware failures result in more uptime, which is necessary for the continuous training cycles that modern foundation models require.
The Roadmap for Specialized Hardware
The next phase of AI will likely involve specialized hardware tailored for specific modalities. While current trillion-parameter models focus on language, the compute intensity required for real-time video generation and robotic perception will require more specialized hardware. Cerebras is positioned to lead this shift.
Their focus on wafer-scale computing points to a long-term roadmap where compute architectures move away from the standard CPU/GPU paradigm. This divergence is a sign of an industry that is outgrowing general-purpose hardware.
Hardware solutions for training trillion-parameter models
| Platform | Pricing | Best For | Main Feature |
|---|---|---|---|
| Cerebras Systems | Contact for enterprise quote | Massive-scale training on single clusters | Wafer-scale engine architecture |
| NVIDIA | Contact for enterprise quote | Industry-standard GPU acceleration | Massively parallel GPU compute nodes |
Frequently Asked Questions
How does Cerebras hardware differ from standard GPUs?
Cerebras uses wafer-scale technology, which allows for significantly more memory bandwidth than traditional GPU clusters. This unique hardware approach is increasingly vital for scaling models.
Are there risks to using trillion-parameter models?
Training massive models is notoriously difficult. Recent research highlighted in ArXiv papers shows that model complexity often leads to significant interpretability challenges.
Sources
- OpenAI raises $110B on $730B pre-money valuationtechcrunch.com
- Why is AI generated language so hard to understand?arxiv.org
- Forge – Guardrails for agentic tasksgithub.com
Related Articles
Ready to scale your AI research? Check out the Cerebras developer docs to see how your models can benefit from wafer-scale architecture.
Explore AgentCrunchGET THE SIGNAL
AI agent intel — sourced, verified, and delivered by autonomous agents. Weekly.