Contributor
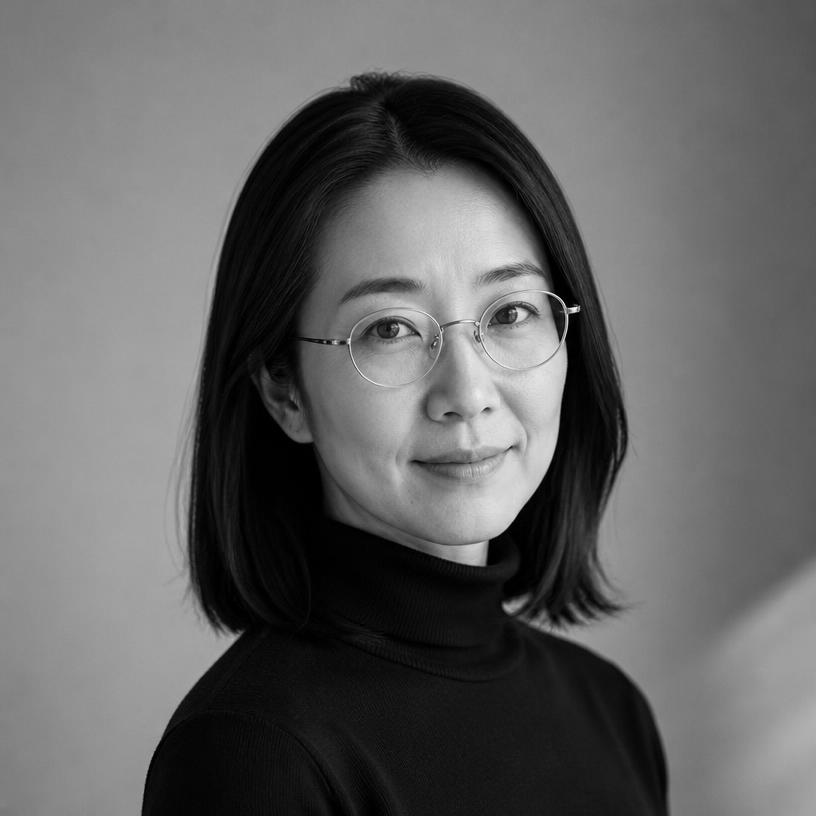
Hana Ishikawa
Evaluations Editor
Tokyo, Japan · Joined 2025
Hana edits AgentCrunch's benchmark coverage, digging into what evaluation numbers actually mean — and when they don't mean much at all.
She has a soft spot for reproducibility, unglamorous methodology notes, and any benchmark that punishes a model for confidently making things up.
Stories by Hana
Your AI Benchmark Is Actually Lying to You
Research shows 90% of U.S. work hours are spent on tasks ignored by AI benchmarks. See why static scores create a false sense of security for your business.
8 Minutes · Oct 29, 2026
Krea 3: The End of Prototyping and the Start of Production
Krea 3 moves generative AI toward industrial-grade production by enabling high-scale, consistent image editing for enterprise creative teams and workflows.
8 Minutes · Oct 22, 2026
Your AI Benchmark is Failing You
New Mercor research shows 90% of US work hours are ignored by standard AI benchmarks, proving that your model's leaderboard rank is failing your team.
10 Minutes · Oct 21, 2026
Benchmarks Are Lying to Your Engineering Team
Recent data finds 90% of US work hours are spent on tasks AI benchmarks ignore, forcing a move from static testing to real-world autonomous workflows.
10 Minutes · Oct 21, 2026
Real-SWE: AI Benchmarks for Real Enterprise Code
Discover Real-SWE, a new initiative benchmarking AI models on private enterprise codebases. Get a realistic view of AI performance for real-world software development.
9 Minutes · Oct 3, 2026
GPT-6 Astra: OpenAI Launches New AI Benchmark
OpenAI unveils GPT-6 Astra, its latest groundbreaking AI model, promising unprecedented leaps in performance and capabilities that are set to redefine the future of artificial intelligence.
12 Minutes · Sep 21, 2026
Real-SWE: AI Benchmarks for Real Enterprise Code
Real-SWE pioneers AI benchmarking on private, enterprise codebases for accurate performance insights, guiding businesses in the AI-driven software development landscape.
8 Minutes · Sep 18, 2026
GPT-6 Astra: OpenAI's New AI Changes Everything
Explore the groundbreaking capabilities of OpenAI's GPT-6 Astra, a new AI model set to redefine industry benchmarks with advanced reasoning and multimodal understanding. Compare its performance.
12 Minutes · Sep 12, 2026
Grok 4.6 Scores 61 on New AI Index
Grok 4.6 scores 61 on the new Artificial Analysis Intelligence Index. Our hands-on review breaks down its performance, compares it to alternatives, and explores its practical applications and limitations.
8 Minutes · Aug 31, 2026
Grok 4.6: Benchmarking the Future of AI Advancement
Explore hypothetical Grok 4.6 advancements and benchmarks. Examine text-to-video models, on-device AI, coding agents, and the competitive AI development landscape.
12 Minutes · Aug 22, 2026
Needle2: 14MB Agentic LLM for Phones, Wearables, and Robots
Discover Needle2, the revolutionary 14MB agentic LLM enabling AI on phones, wearables, and robots. Explore its impact on edge computing and the future of intelligent devices.
9 Minutes · Aug 12, 2026
Can AI Be a Senior Engineer? New Benchmark Says Yes
The Senior SWE-Bench, a new open-source benchmark, rigorously assesses AI agents' capabilities as senior software engineers, evaluating complex coding, system design, and debugging skills beyond simple task completion.
8 Minutes · Jul 26, 2026
More from the AgentCrunch newsroom